Company
What we build, and why
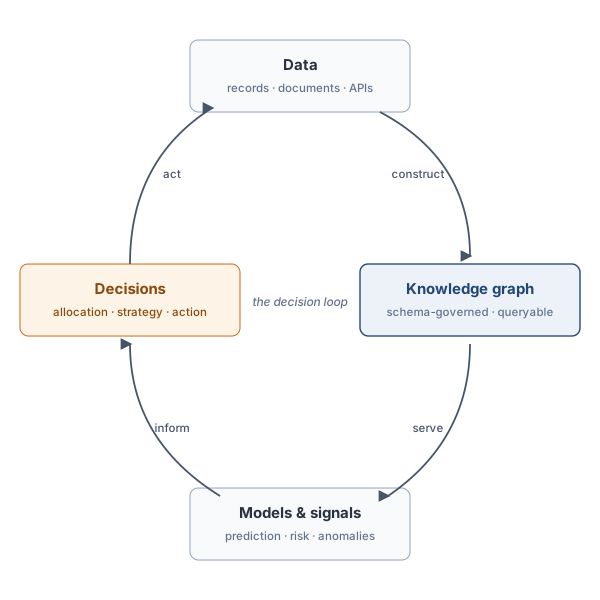
Most operational data is relational at heart — clients, projects, contracts, publications, and the links between them. It lives in tables and documents that keep those relationships implicit, so every serious question about the whole turns into an integration project.
GrowGraph builds the engines that make the relationships explicit. GraFlo transforms structured records into schema-governed knowledge graphs, portable across eight database backends. OntoCast extracts auditable facts from documents, guided by an ontology. The OntoCast API Platform runs that pipeline as a managed service.
On top of the graph we build decision models — claim scoring, anomaly detection, portfolio construction — the applications described in our research and finance work. The graph closes the loop between the data a business produces and the decisions it makes.
Verifiable
Don't take our word for it
The engines are published — evaluate them before you ever talk to us.
Published and citable
GraFlo is released on PyPI and archived with a DOI (10.5281/zenodo.15446131) — you can pin the exact version you evaluated and cite it.
Zenodo record
Code you can read
OntoCast and GraFlo are both open source (Apache-2.0). Every claim on this site can be checked against the repositories.
github.com/growgraph
Documented in public
Architecture, schema language and backend support are specified in the public documentation — not in a sales deck.
GraFlo documentation


Get in touch
Talk to the team
Questions about the tools, the platform, or a use case we haven't written up? We read everything sent to team@growgraph.dev.